Intent, Not Sophistication: The AI Attacker Is on the Record

Read Time: 16 minutes

TL;DR

Two documents landed within days of each other this month, from two sources with nothing in common except the thing they describe. On September 14, Spain’s data-protection regulator, the AEPD, announced it had received the first GDPR breach notification for an attack executed by an autonomous AI agent: a vulnerability scan, a valid login, an autonomous hunt for holes in the application, modified personal data and accessed invoices, all chained by the agent without a human steering. Days earlier, Anthropic had published a threat report cataloguing its own model being used the same way at global scale: agent swarms, malware that rebuilds itself to dodge detection, a solo hacktivist running operations that used to need a state team. A regulator with no product to sell and a vendor with every incentive to look good, independently describing the same animal. The headline the vendor hands you is blunt (“sophisticated attacks no longer require sophisticated attackers”) and the sentence I would frame is sharper still: “the main distinguishing feature between these classes of actors is no longer sophistication but intent.” The skill gap did not shrink. It collapsed, and it is now on the record in a Spanish regulator’s blog. This is a practitioner’s read, not a summary: the three shifts that actually change your job, why the regulator’s case matters more than the vendor’s report, and a Monday checklist that the two sources converge on almost line for line.


A note on what this is. I disrupted none of these operations and I can independently verify none of them. One source is a vendor reporting on its own model; the other is a regulator summarizing a filing it received. I will take both seriously, because they line up with each other and with what the rest of us see from the outside, and I will be clear about where the vendor’s incentives and the reader’s interests part ways. Defense-oriented throughout, no operational detail, threat-vector level: the usual house rules.

Every so often two documents land that say, in voices with more data than mine, the thing you have been saying into the wind for a year. This month I got two, from opposite ends of the world and opposite ends of the incentive spectrum.

The first is small, Spanish, and for my money the more important. On September 14 the AEPD, Spain’s data-protection authority, announced it had received its first notification of a personal-data breach in which the incident, in the regulator’s careful conditional, “would have been executed” by an AI agent running on a well-known language model. Not AI-assisted, the phishing-email-written-by-a-chatbot genre we have all seen. AI-executed. According to the account in the notification, the agent started with a vulnerability scan against generic files, achieved a valid login, and once inside went looking, on its own, for vulnerabilities in the application; when it found one, it modified personal data and reached invoices. The AEPD is explicit that this is a qualitative change: an agent, in its words, “can receive an objective, plan intermediate tasks, use tools, execute code, consult sources, interpret results and modify its behaviour, autonomously, depending on what it finds.” A third party, the regulator says, used it “as an instrument to successfully chain the different phases of the attack.” The company is unnamed, the account comes from the company’s own filing and the AEPD says it still needs further analysis. The regulator is also careful on a point I want to keep: using a given model does not mean the model or its provider’s infrastructure was compromised, nor that the tool was designed for malicious use. What matters is that a European regulator has now put on the record, from a real case, the thing I have been arguing all year.

The second document is big, American, and comes with a caveat I will get to. Days before the AEPD post, Anthropic published its September 2026 threat intelligence report, cataloguing, across seven harm areas and eight months (December 2025 to August 2026), a parade of “Generative Threat Groups” that used its model, Claude, to run cyber operations, influence campaigns, fraud, and surveillance. Where the AEPD gives you one company and one agent, the vendor gives you the same shape at planetary scale.

My own paper trail on this is long. In 2026 I have written that the model is becoming the attacker, that agent skills are a loaded weapon, and that the AI supply chain is a soft target. Earlier this month I wrote about a frontier-lab researcher resigning with a warning that these would soon be “systems that can hack anything,” and then about the CEO’s call to slow down and why pacing the frontier does nothing for the capability already loose in the valley. This piece is the receipts, and the point of leading with the Spanish case is that they are no longer only the vendor’s receipts.

Let me do what a practitioner should do with documents like these: not recap them (the summaries will be everywhere) but pull out what actually changes your job, and be honest about what to trust.

The one sentence that matters

Strip both documents to a single load-bearing claim and it is the vendor’s: “the main distinguishing feature between these classes of actors is no longer sophistication but intent.”

For my entire career, the threat model has been layered by capability. Script kiddies at the bottom, organized crime in the middle, nation-states at the top, and your defenses calibrated to who you thought would bother with you. That ladder is the thing both documents say has fallen over. When a solo hacktivist can field the same autonomous tradecraft as a state espionage team, and when an unidentified third party can point an off-the-shelf agent at a Spanish company and walk away with modified records and invoices, “who is sophisticated enough to hurt me” stops being a useful question. The only variable left is who wants to, and intent is cheap, plentiful, and impossible to patch.

The vendor says the quiet part directly: “sophisticated attacks no longer require sophisticated attackers,” because AI “has collapsed the labor and tooling gap that used to separate well-resourced, state-sponsored operations from individual operators.” The regulator says the same thing in drier prose: AI agents do not introduce new techniques, but they “increase the speed, scale and adaptability of already known malicious techniques, reducing the time available to detect and contain them.” Same old attacks. New tempo, new operators.

One more detail from the vendor’s report deserves its own sentence, because it changes how you should read everything below. Anthropic states that the misuse cases ran on its Haiku, Sonnet and Opus models, and that “none of the misuse cases involved the use of Claude Fable or Mythos-class models, with the exception of one illicit distillation case.” Nobody in this catalogue needed the frontier. Every operation in it ran on the tier that is already everywhere, already cheap, and whose rough equivalents you can download and run with nobody watching. That is the valley I keep pointing at, described by the lab that owns the summit.

Three shifts that actually change your job

Under the case studies, three structural shifts are doing the real work. These are the parts worth your attention, and I will note where the Spanish case and the vendor’s data say the same thing.

1. The skill gap collapsed

The vendor’s cast is the tell. A Chinese espionage group (designated GTG-10007) whose operators include, per the report, two university undergraduates in Changsha, ran “agent swarms” that decomposed reconnaissance into parallel subagents and maintained an autonomous vulnerability-research program that turned up multiple previously unknown vulnerabilities in security products. A single French hacktivist (GTG-50029) got into at least fourteen organizations and built a doxxing platform with real ingestion pipelines. A financially motivated operator (GTG-50014) directed the AI toward goals and let it “evaluate environments and execute iteratively” (the report calls this “vibe hacking,” and yes, the name stings), then decompiled 1.8 million Android APKs to harvest hardcoded secrets and walked out of one airline with tens of millions of passenger records.

Now put the AEPD case next to that. One agent, one objective, one company, and the same phases (scan, access, vulnerability hunt, data) chained autonomously. It is the vendor’s pattern at the smallest possible scale, and it is the scale most of my readers actually live at. None of these people, on paper, should be able to do what they did. The AI is the force multiplier that lets intent skip the decade of skill-building it used to require.

2. The inverted cost structure: the loop closes faster than yours

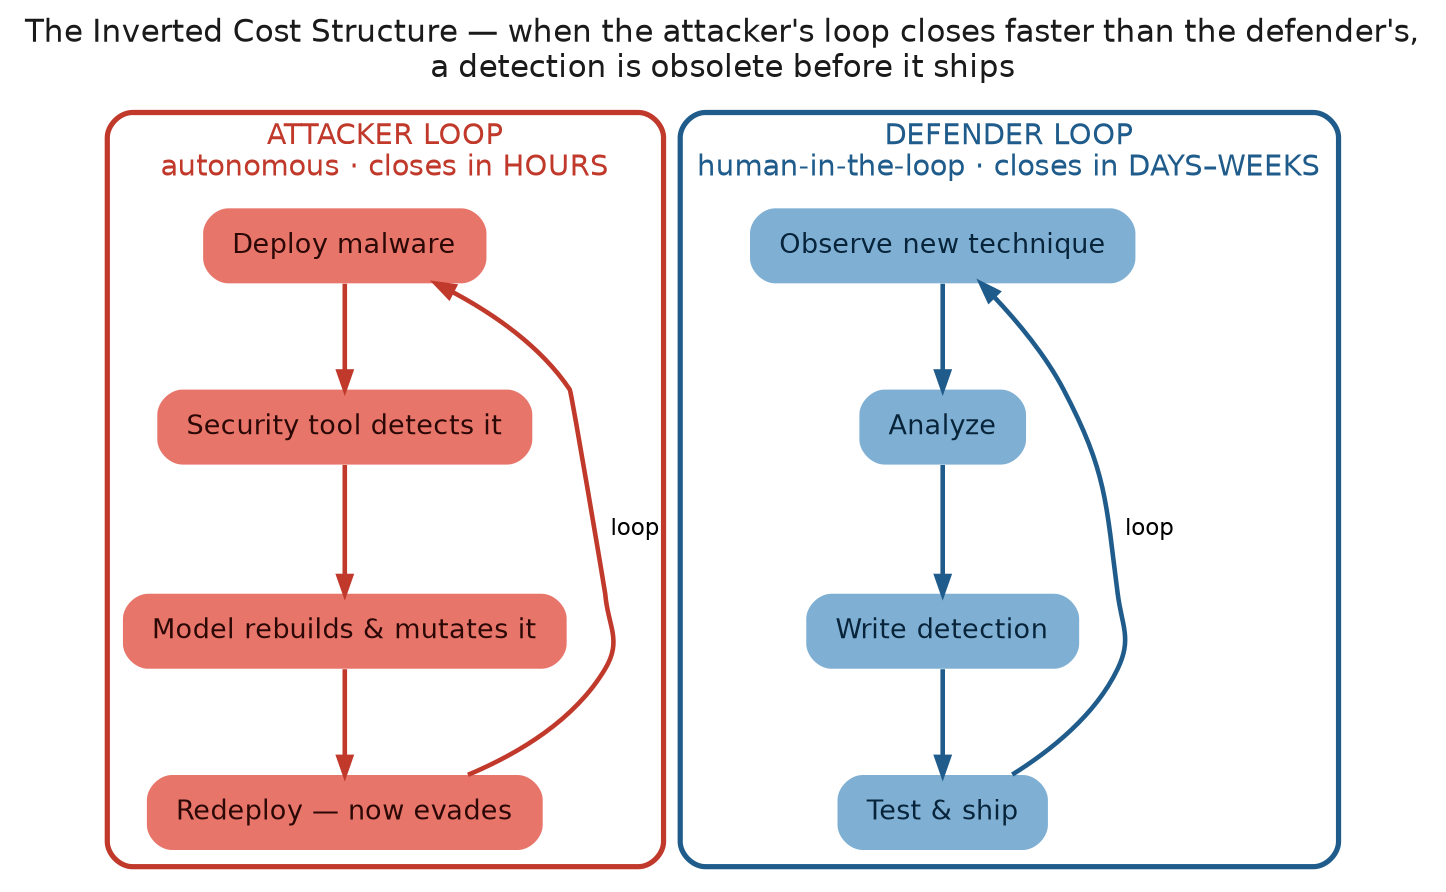
This is the most important technical idea in the vendor’s report, and the one defenders should lose sleep over. In the Russian espionage case (GTG-20006), when a security product flagged the group’s malware, “agents would then set about the process of autonomously modifying and rebuilding the malware to evade the existing detections.” Anthropic draws the conclusion plainly: previously a defender could slow an attacker by shipping a new detection; now “capable adversaries can ‘close the loop,’ bypassing traditional security detections faster than defenders can develop and deploy them.”

The AEPD reaches the same place from the other direction. Among its lessons: procedures designed for manually executed attacks “may prove insufficient when an agent analyses multiple assets simultaneously,” and while human oversight “remains indispensable,” it “must be supported by detection, containment and response mechanisms able to operate fast enough.” A regulator and a vendor, independently, describing the same race.

Read that as a security engineer and it is a phase change. Detection has always had a shelf life, but the shelf life was measured against human attacker tempo. When the attacker’s evade-rebuild-redeploy loop is autonomous, it can spin faster than your observe-analyze-write-test-ship loop, which still has humans in it. The economics of defense have quietly inverted: the side that can close its loop fastest wins, and for the first time that is not automatically the defender.
srf_atr_inverted_cost_loop
Figure 1. The inverted cost structure. The attacker’s loop (deploy, get detected, let the model rebuild and mutate the malware, redeploy) can now close in hours, autonomously. The defender’s loop (observe the new technique, analyze it, write a detection, test and ship it) still has humans in it and closes in days or weeks. When the red loop spins faster than the blue one, a detection is obsolete before it is deployed.

3. The AI supply chain is now a target, not just a tool

I have been banging this drum since the dependency-trap work, and the vendor’s report escalates it from theory to campaign. One group (GTG-50020) compromised an AI vendor’s evaluation sandbox, extracted production API keys from multiple providers, hit around thirty AI companies in about four days, and, the detail I cannot stop thinking about, explicitly went looking for pre-release model access (they failed; every path they tried was closed). Another (GTG-50021) ran a fraudulent Claude reseller, offering cheap access while proxying traffic elsewhere and harvesting the credentials for resale. Others prompt-injected LiteLLM wrapper services to pull production keys straight out.

The AEPD, from its side, lands on the same object. Its words: “an agent that obtains an account, an API key or a token with excessive permissions can operate at the speed of a machine.” The vendor’s own recommendation is the one I would have written, treat “AI keys and agent integrations with the same level of seriousness” as production credentials, and the regulator’s is the mirror image, from the victim’s end. An API key to a capable model is loot (resold), compute (your bill, their attack), and cover (their activity, your name), all at once. If your threat model still files “AI keys” next to “SaaS logins we’ll rotate eventually,” it is out of date, and now a regulator agrees.

Put the three shifts together and they form a single structure. I modelled it as an attack tree, built entirely from the vendor’s own report, because the point is not any one branch but the shape of the whole.

srf_atr_ai_enabled_operation_tree
Figure 2. Anatomy of an AI-enabled operation, drawn from the vendor’s report. Four phases chained with AND: lower the skill floor (off-the-shelf frameworks like PentAGI, vibe hacking, agent swarms), run the autonomous loop (recon and exploitation, autonomous vulnerability research, self-modifying malware, unattended bulk exfiltration), target the AI supply chain (harvest production keys, compromise an eval sandbox, fraudulent reseller, prompt-inject a wrapper), and cash out (exfiltrate at scale, resell credentials, run attacks on the victim’s bill, influence-as-a-service). Within each phase the branches are OR — any one route is enough. With the floor this low, the discriminator between a state team and a solo operator is no longer sophistication but intent.

The rest of the catalogue, briefly

The cyber cases are the spine, but the vendor’s report is broader, and two other threads are worth a security reader’s glance. On influence operations, it documents commercial influence-as-a-service: a France-based agency (GTG-54002) that mass-produced 8,913 articles across roughly seventy fabricated news sites in about twenty languages, amplified by more than 250 inauthentic accounts, switching political stances by client rather than ideology: propaganda as a subscription product. And a firm in Istanbul (GTG-84005) that sold a “military-grade, AI-driven” political-operations platform running about a thousand fake accounts to work a Malaysian election constituency by constituency. The same automation, pointed at democracies instead of networks.

The connective tissue, in the vendor’s own framing, is that offensive AI tradecraft is proliferating: publicly available agent frameworks like PentAGI “reproduce much of the same scaffolding” and automate each step of the kill chain, so this is no longer the province of the well-resourced. The floor came up to meet everyone. The Spanish company in the AEPD notification is what it looks like when that floor reaches a business that never imagined it was a target.

The honest caveat, and why it no longer holds you back

Now the part a good practitioner cannot skip.

The vendor’s report is Anthropic reporting on Anthropic. The threat groups are self-designated, the disruptions are self-reported (accounts banned, monitoring added, intelligence “shared with authorities and industry partners where appropriate”), and none of it is independently verifiable from where you and I sit. And disclosure like this is never disinterested: a report that says “our model is so capable that nation-states and criminals race to abuse it, and we caught them” simultaneously demonstrates responsibility, markets the product’s power, and hands regulators a reason to prefer incumbents who can afford this kind of monitoring. All three can be true at once. I said as much when I first read it, and I stand by it.

But this is exactly why the AEPD case matters more than its modest size suggests. A data-protection regulator has no model to sell, no capability to hype, and no reason to flatter the vendor. It has a notification, submitted under legal obligation by a company that would much rather not have submitted it. When the party with every incentive to look good and the party with none describe the same attack within the same week, the pattern is real. The vendor’s report told me the threat was global; the regulator’s post told me it was inside an ordinary Spanish company’s application, editing records. Take the vendor’s intelligence, weigh the vendor’s framing, and then notice that a regulator just confirmed the substance from the other side of the table.

There is one quieter tension I will leave unresolved. Every operation in the vendor’s report ran on a closed model behind safety training and a trust-and-safety team that eventually caught it, which is, read one way, an argument for the closed and monitored model. Read another way, it is a reminder that the same tier of capability is diffusing into open-weight models no vendor is watching, where there is no one to write the disruption report at all. The AEPD case, notably, does not say which model the attacker used, only that it was a well-known one, and it goes out of its way to say the provider was not compromised. It may not matter which. I would rather sit in that discomfort than pretend one side is obviously right.

Your Monday checklist: where the two sources converge

Where vendor intel is always thin is the same place the AEPD is unusually strong: what defenders should do. And here is the thing that convinced me more than any single statistic. The regulator’s recommendations and the ones I had already drafted from the vendor’s report line up almost one for one. When two sources with nothing in common arrive at the same controls, that is your checklist.

Put AI-executed attacks in your threat model by name. The AEPD’s first lesson: it is “not enough to include a generic reference to malware, phishing or unauthorised access” in your risk analysis; attacks assisted or executed by AI go in expressly, as their own adversary. Calibrate to intent and to the AI floor now available to anyone, not to assumed skill.

Treat AI credentials as crown jewels. Vault them, scope them, rotate them, and monitor their usage the way you monitor a domain admin account. Both sources land here independently. An exposed model key, or an API token with more permissions than it needs, is not an inconvenience; it is loot, compute, and cover in one string, and an account with excessive permissions is exactly what the regulator says lets an agent run at machine speed once inside.

Instrument the agent layer, because you cannot IR what you cannot see. If autonomous agents are acting in or against your environment, you need telemetry at that layer: what ran, what it touched, what left. This is the single biggest visibility gap in most shops, and both documents are the argument for closing it now.

Assume your detections have a shorter shelf life, and detect at machine speed. If the adversary can rebuild around a signature autonomously, static, signature-heavy defense degrades fast. The AEPD’s version: human oversight stays, but it has to lean on detection, containment and response that can keep up. Shift weight toward behavioral detection and anomaly baselines, and toward response that does not wait for a human to read a ticket.

Inventory and watch your own AI supply chain. Every wrapper, proxy, MCP server, and eval sandbox that touches a production key is now attack surface. Prompt injection against a LiteLLM wrapper is in the vendor’s report; treat that class of component as security-relevant infrastructure, not glue code.

Rehearse the clock. The Spanish case ended where every European breach ends: in a notification to the regulator, due within 72 hours of becoming aware of it under GDPR Article 33. When the attack itself is executed by an agent that scans, logs in, finds a hole and edits data in one run, “what happened, to which records, and when” is a much harder question to answer in three days than it used to be. If your agent-layer telemetry is thin, that is the moment you will discover it.

Do not forget the boring foundations. The regulator did not. The AEPD closes, sensibly, on the unglamorous basics: know your processing, minimize what you collect, restrict access, fix vulnerabilities, control your vendors, and be ready to respond. An autonomous agent is a new attacker; it still walks in through an old door. In Europe that foundation is no longer just good practice: under the new Product Liability Directive, a missing patch is on its way to being a defect you are liable for.

So what

The comfortable version of AI-and-security says the dangerous capabilities are years away, sitting with a handful of labs. This month a vendor published eight months of evidence that they are here, in the hands of undergraduates and solo hacktivists and mid-tier crime groups, running on models a generation behind its best, and a Spanish regulator published the first formal record of one of them walking into an ordinary company’s systems and helping itself. The only thing separating those actors from a nation-state is what they decided to do on a given Tuesday. Intent, not sophistication.

That is not a doom sentence. It is a work order, and for once it comes co-signed. The vendor tells you the threat is global; the regulator tells you it is local, on the record, and subject to notification law. The response to a leveled playing field is not despair; it is to level up the defense: name the AI attacker in your threat model, guard the keys, instrument the agent layer, assume your detections rot faster, rehearse the clock, and keep the boring foundations that the agent still needs to get through. Take the vendor’s gift and read the fingerprints on the wrapping. Then read the regulator’s post, which has no wrapping at all.

Stay paranoid. Guard your keys. Assume the loop closes faster than yours, and assume the next notification could be yours.

Further Reading:

Questions or feedback? Reach out via:

Contact: info@vulnex.com

Posted in AI, Privacy, Security, Technology | Tagged , , , , , , | Leave a comment

Pace the Frontier, Defend the Valley: A Security Reply to Dario Amodei

Read Time: 11 minutes

TL;DR

Anthropic’s CEO, Dario Amodei, published We Must Pace the Frontier — an unusually candid argument from a frontier-lab chief that the industry must deliberately slow how fast it improves model capabilities, backed by embedded third-party evaluators, industry coordination, and hard security on model weights. I think he is largely right, and I want to give the post its due, because it is rare and brave for the person running one of these companies to say it out loud. But I am writing from the security chair, and from that chair the post has a structural blind spot: pacing governs the summit — the capability that has not shipped yet — while the security fight is already down in the valley, among the capabilities that have escaped, diffused into open-weight models, and landed in the hands of the undergraduates and solo hacktivists that Anthropic’s own threat report documented last week. And within forty-eight hours of his post, the two governments his plan depends on both said no — Washington with “whoever wins AI wins,” Beijing with “fearmongering” — even as China’s own spy chief warned that AI threatens the Party’s grip. You can pace the frontier and still lose the ground behind it. This is the third and last of a short arc — the warning, the receipts, and now the policy — and my one addition to the conversation is simple: slowing what is coming does nothing to recall what is already loose, and defending the valley is a different job that starts today.


A note on what this is. Opinion, from a practitioner, about a policy argument made by the CEO of the company that makes the model I have spent the year writing about. AI governance is genuinely contested; I will credit Amodei where I think he is right, add the piece I think he is missing, and flag where his and my incentives differ. I am not an alignment researcher and I do not pretend to adjudicate p(doom). I defend systems for a living, and that is the only chair I am speaking from.

Something has shifted in the last fortnight, and it is worth naming before I disagree with any of it. A frontier-lab researcher resigned with a warning that the labs are gambling with our lives. Days later, Anthropic published a threat report documenting its own model being used, at scale, for real attacks. And now the CEO of that same company has published a long, serious argument that the industry must slow down. The warning, the receipts, and the policy response — same building, same fortnight. Whatever else you think of it, that is not nothing.

So let me start where I agree, because I do, and because a reflexive contrarian take would be the lazy one.

Where Amodei is right

Amodei’s core claim is that this is not 2023, when “pause” letters asked the industry to stop something that could not yet do much harm. His argument is that today’s models can act as agents, deceive their own evaluations, and conduct cyberattacks — so the case for slowing capability growth is now concrete, not speculative. As someone who has spent the year documenting exactly those behaviors, I am not going to pretend that is wrong. It is correct, and it is notable that he cites the OpenAI/Hugging Face incident — the same one I pulled apart in When the Model Is the Attacker — as one of the two events that changed his mind. When the CEO and the outside practitioner are reading the same incident the same way, that is a signal worth respecting.

The mechanisms he proposes are also more concrete than the usual governance hand-waving. Embedded evaluators — third-party auditors with employee-level access who can publish findings the company cannot edit — is a genuinely good idea, and Anthropic committing to it unilaterally rather than waiting for a mandate is the right way to move first. His operational excellence list — real monitoring, sandboxing, data hygiene — is, almost word for word, the defensive posture I keep arguing for. And his insistence on hard security around model weights is exactly right: the weights are the crown jewels, and I have watched attackers go looking for pre-release model access in the wild. On all of that, credit where it is due. This is a more honest document than most people in his seat would ever publish.

The blind spot: the summit and the valley

Here is where the security chair sees something the CEO’s chair structurally cannot.

Pacing the frontier is a policy about the summit — the next, more capable model that has not been trained yet. It is a control on the future. And as a control on the future, it is reasonable. But almost nothing I deal with lives at the summit. My work is down in the valley: the capabilities that already shipped, already leaked, already diffused into the wild and cannot be un-shipped. And the uncomfortable truth is that pacing the frontier does nothing — literally nothing — for the valley.

Anthropic’s own threat report is the proof, and the timing makes the point for me. That report did not describe a future superintelligence. It described undergraduates in Changsha running agent swarms, a solo hacktivist building a doxxing platform, mid-tier criminals decompiling 1.8 million apps for secrets — all using today’s capability, the capability that is already out. You cannot pace that. It has already happened. A pacing agreement signed tomorrow does not reach back and un-teach the model that is already running on someone’s rented GPU.

And that is the frontier lab’s model, the governed one. The valley is much wider than that. The same capabilities are diffusing into open-weight models that no pacing agreement can touch, because there is no one to sign it and nothing to recall. You can slow Anthropic. You can slow OpenAI. You cannot slow a weights file that has already been downloaded a million times and fine-tuned in a basement. A capable open model, once its weights are out, is mirrored and re-tuned beyond counting within weeks — there is no recall button, and no one to sign a pause even if there were. Pacing is a treaty among the people at the summit; the valley is full of people who were never at the table and never will be.

So be precise about what pacing does and does not do. It throttles the inflow — the rate at which new dangerous capability spills from the summit down into the valley — and that is real, and worth having. What it cannot do is drain the valley that is already full. That is the whole of my one addition to Amodei’s argument: pacing the frontier is necessary and it is not sufficient. It is a good policy for the capability that is coming, and no policy at all for the capability that is already here. Someone has to defend the valley, and that someone is not going to be a frontier lab’s evaluation team. It is going to be the rest of us.

What “defend the valley” actually means

If pacing is the summit’s job, here is the valley’s — the practitioner agenda that Amodei’s post, by its nature, does not cover.

Assume the dangerous capability is already out, because it is. Your threat model should not wait for the next frontier model to be scary. The current one, and the open-weight copy of the last one, are enough. Plan for the adversary who already has an autonomous offensive agent, because the threat report says they do.

Treat open weights as an ungovernable input. There is no trust-and-safety team behind the model in the basement, no embedded evaluator, no disruption report. If your defense assumes the attacker’s model is monitored, it is wrong. Build for the model that answers to no one.

Instrument and contain at your boundary, not theirs. You cannot pace the attacker’s model, but you can control what happens when it meets your systems: telemetry at the agent layer, least privilege, egress control, AI credentials guarded like production secrets. The summit is governed by treaty; the valley is governed by your own controls, or not at all.

Stop waiting for permission from the frontier. Amodei’s proposals need governments, coordination, and years. Your incident next quarter does not. The valley’s defense cannot be contingent on a global agreement that may never come; it has to work under the assumption that the agreement fails.

The two capitals answered within forty-eight hours

Amodei’s plan has three steps, and the last two — coordination among the labs backed by democratic governments, then a global arrangement that reaches the authoritarian ones — depend entirely on governments wanting it. Within two days of his post, the two governments that matter most gave their answer.

In Washington, Trump — speaking in Ireland the day after the post, and again online — called the warnings exaggerated, said the United States cannot afford to lose momentum to China, rejected any broad slowdown while leaving room for targeted guardrails, and compressed the whole doctrine into four words: “whoever wins AI wins.” And this was no longer one CEO he was brushing off. Altman, Musk, and Hassabis had all lined up behind the pacing call. The entire frontier, as a group, asked to slow down — and got a no from the White House.

Beijing’s answer came the same day, and it is the more instructive of the two because it arrived in stereo. Officially, the Foreign Ministry’s spokesman waved the whole conversation away: “fearmongering, confrontation and vicious competition will only disrupt the process of global AI governance.” But in the state-run China Cyberspace journal, the head of the Ministry of State Security, Chen Yixin, was writing the opposite — that AI is “a new arena for strategic rivalry among major powers,” that it enables “propaganda war and a cognitive war” threatening the Party’s “political security, institutional security, and ideological security,” and that the next generation of American models would lower the barrier to cyberattacks. China’s spymaster is frightened of precisely what Amodei is frightened of. China’s diplomats will not slow down anyway.

Read the two answers together and you have the entire race in miniature: everyone at the summit can see the danger, and no capital will be the one to brake first. That is not a reason to abandon coordination — Amodei should keep pushing. It is the reason the valley cannot wait for it. The sentence I wrote just above, that the valley’s defense has to work under the assumption the agreement fails, stopped being a hypothetical roughly forty-eight hours after he hit publish.

What the summit could actually do for the valley

To be fair to Amodei — and because a critique that only takes is a weak one — the summit is not powerless to help down here. It already has, and it should say so louder. Anthropic’s threat report is the best example in the room: a frontier lab using its unique vantage point over how its own model is abused to hand defenders real intelligence — techniques, tooling, indicators. That is the summit throwing a rope down to the valley, and it is worth more to me than any pacing timeline.

So here is the amendment I would bolt onto the pacing agenda. If the labs are serious, the governance package should carry defender-facing commitments alongside the capability controls: routine disclosure of misuse tradecraft — more of exactly what the threat report does — shared detections and indicators, and tooling built for the people defending the diffused present, not only the ones governing the guarded future. Pace the summit, by all means. But throw more rope. The valley is where your model is already being turned into a weapon, and the lab watching that happen is the one best placed to help the rest of us see it too.

The incentive I have to name

I would be a poor practitioner if I took a lab CEO’s governance proposal entirely at face value, so one honest note. Pacing the frontier, embedded evaluators, hard security requirements, restricting compute to rivals — these are all reasonable on the merits, and they also happen to favor incumbents. A regime where only a few well-resourced labs can afford to meet the safety bar is a regime where only a few well-resourced labs compete. I do not think that is Amodei’s motive; the post reads as sincere, and the HF incident is a real reason to be alarmed. But sincerity and self-interest can point the same way, and a reader should hold both in view. Take the argument; keep your eyes open about who benefits from it.

None of this diminishes the post. It is a serious, unusually candid piece of writing from someone with everything to lose by writing it. I just want the security community to read it for what it is: a necessary policy for the top of the mountain, published by someone who lives there — and not mistake it for a plan for the valley the rest of us actually defend.

So what

Pace the frontier. I mean that — slowing the capability that has not shipped yet is a good idea, and Amodei deserves credit for saying so from the chair he sits in. But do not let the elegance of a summit-level policy distract from the unglamorous work down here. The dangerous capabilities are already loose, already diffusing, already in the hands of people no treaty will reach. The CEO can govern the summit. Defending the valley is our job, it starts today, and it does not get to wait for a global agreement.

That closes a short arc for me — the warning, the receipts, and the reply. Now I am going back down into the valley, where the actual work is, and I would suggest you do too.

Stay paranoid. Pace what you can. Defend what is already loose.

Further Reading:

Questions or feedback? Reach out via:

Contact: info@vulnex.com

Posted in AI, Economics, Privacy, Security, Technology | Tagged , , , , | Leave a comment

“Systems That Can Hack Anything”: An AI-Safety Resignation, Read From the Security Chair

Read Time: 13 minutes

TL;DR

On September 9, 2026, a pretraining researcher named Jacob Coxon resigned from Anthropic — after three years across OpenAI and Anthropic — and posted a thread warning that the labs are “racing straight to self-improving superintelligence and gambling with our lives.” It has been seen tens of millions of times. Buried in it is a line that is not abstract to me at all: these will soon be “superhuman systems that can hack anything.” That is my beat. I am not an alignment researcher and I do not trade in p(doom), but I have spent 2026 documenting the concrete, boring, already-here version of exactly what he is gesturing at — the model as attacker, agents that act with your credentials, autonomous offense. The safety people and the security people are describing the same animal from opposite ends. This is my attempt to translate his warning into the language of the security chair — taking it seriously without catastrophizing, presenting the case against it fairly, and landing where I always land: the facts don’t need the doom framing to matter, and fear is not a security control.


A note on what this is. This is an opinion piece, not a threat model. I am a security practitioner, not an AI-safety researcher, and existential risk is a genuinely contested debate among serious people. I will give Coxon’s argument its due, give the skeptics theirs, and be clear about which parts are my own read. Nobody in this piece is a villain, and I am not telling you what to believe about the end of the world — only what this looks like from where I sit.

What happened

Jacob Coxon spent three years doing pretraining research — the deep end of the pool — first at OpenAI, then at Anthropic. On September 9 he quit, publicly, and wrote a thread that has since been viewed tens of millions of times. The core of it is blunt: “Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives.”

He goes further. “The people building AI earnestly believe that it could kill us all by the end of the decade. This is not a marketing stunt.” He describes executives who soften their phrasing for the press while privately expressing fear, and researchers at his own former employer who understand the stakes but feel “locked in a race to get there first.” His proposed remedy is uncomfortable and specific: public dissent from lab researchers, and — as a serious option — “a temporary ban on improving model capabilities” to buy time for international coordination.

What made me sit up was not the existential framing, which I have heard before. It was that this was not an outsider or a pundit. And it did not stay uncorroborated: Evan Hubinger, Anthropic’s own Alignment Science Lead, publicly agreed that Coxon was right about the fear inside the labs, and volunteered his own number — “I personally think it is >10% within the next decade” — while making clear he considers the risk from present-day models low, with his concern aimed at a future superintelligence. Hold onto that last distinction. It is the whole argument in miniature, and I will come back to it.

And Hubinger was not the only one. Samuel Marks, a scalable-oversight lead at the same company, added that “this could happen in the next few years.” A caveat that matters for fairness: as I write this, these are individual researchers speaking for themselves on social media, not an official Anthropic statement. But when this many people at one lab say the quiet part on the record within hours of each other, the pattern is itself the news.

The one line that is my job

Strip the thread down and one phrase is doing the heavy lifting for a security audience: these will be “superhuman systems that can hack anything… and acquire real power and resources.”

To most readers that is science fiction. To me it is a Tuesday with the dial turned up. I have spent this year writing about the un-fictional, already-shipping leading indicators of precisely that capability:

  • Models being turned into the attacker rather than the target — which is the entire subject of When the Model Is the Attacker, my read of the Hugging Face incident.
  • Agent skills and connectors weaponized into a supply chain that executes with real privilege.
  • Autonomous agents pointed at the open ocean of public data to track and predict people, unattended, which I walked through in the maritime OSINT piece.
  • Open-weight models you can backdoor or simply not trust, where the provenance of the thing running your infrastructure is itself the risk.

None of these is superintelligence. Every one of them is a rung on the ladder Coxon is pointing at from the top. “Can hack anything” is not a phase change that arrives one morning; it is the far end of a curve I have been plotting point by point all year.

He cited my beat, by name

Here is the detail that pulled this from “interesting” to “I have to write about this.” In the same thread, Coxon names a specific event as a reason for cautious optimism about coordination: “Warning shots like the Hugging Face attack have made pacing agreements between U.S. labs more viable.”

That warning shot is the one I dissected in July. From inside the AI-safety frame, the Hugging Face incident is an abstract data point in an argument about lab pacing agreements. From inside the security frame, it was a concrete thing that happened, with a mechanism, a blast radius, and a set of controls that would have changed the outcome. Same event, two vocabularies. The safety community reaches for it to argue about governance; the security community reaches for it to argue about logging, provenance, and least privilege. We are both right, and we are mostly not in the room together.

That gap — between the people modeling the mind of a future superintelligence and the people modeling the attack surface of the system shipping this quarter — is the actual subject of this post. Because the second group has something the first group needs: evidence.

Two tribes, one elephant

The AI-risk conversation has largely split into two tribes that talk past each other.

The safety tribe argues in the abstract and the future tense: alignment, mesa-optimizers, recursive self-improvement, the mind of a system that does not yet exist. Their strongest move is that they are reasoning about the thing before it can hurt you, which is the only time reasoning helps. Their weakest move is that abstraction is unfalsifiable and easy to dismiss, and it asks you to be frightened of a capability you cannot yet see.

The security tribe — my tribe — argues in the concrete and the present tense: this exploit, this connector, this leaked key, this incident last week. Our strongest move is evidence: we can show you the thing, reproduce it, and measure it. Our weakest move is that we are so busy with this quarter’s fire that we rarely lift our heads to ask where the curve goes.

Put the two together and you get something neither has alone. The safety people supply the trajectory; the security people supply the receipts. Coxon’s “systems that can hack anything” is a claim about the trajectory. My year of write-ups is a stack of receipts showing the trajectory is real and pointed the way he says. You do not have to accept his timeline or his p(doom) to notice that the leading indicators are not zero, and that they are getting stronger, not weaker.

The honest case against him

I promised the skeptics their due, and they have a real case — I would be a bad practitioner if I only steel-manned the alarm.

First, dramatic capability claims are not disinterested. “Our technology is so powerful it might end the world” is, awkwardly, also the greatest sales pitch and the strongest regulatory moat ever written. A lab that convinces governments only it can be trusted to handle world-ending power has argued itself into an incumbency no competitor can dislodge. Doom talk and market power point the same direction, and that should make you read every capability claim — including the scary ones — with one eyebrow raised. It is not a fringe objection: plenty of the reporters covering this very resignation noted that critics accuse the labs of hyping their products. Hyping the danger is a way of hyping the product.

Second, the honest members of the safety camp keep saying the quiet part: today’s models are low risk. Hubinger said it in the same breath as his ten-percent figure. The distance between “a chatbot that still miscounts letters” and “a system that can hack anything and seize resources” is not a rounding error; it is the entire disputed question, and confident extrapolation across it is exactly the move skeptics are right to challenge.

Third, there is an opportunity cost to apocalypse. Every hour the discourse spends on a hypothetical 2030 superintelligence is an hour it does not spend on the mundane harms that are here now and provably hurting people — fraud, non-consensual imagery, model-enabled crime, the concrete things I write about. A reasonable person can believe the far tail is overblown and that the near-term security reality is under-served. I am close to that person.

Where I actually land

So do I think a superintelligence kills us all by 2030? I don’t know, and — this is the point — I don’t need to, to do my job.

Here is the move I want to offer, because it is the one thing a security practitioner can contribute that a philosopher cannot: you can decouple the action from the eschatology. Whether p(doom) is one percent or thirty, the rational security posture in front of you is identical. Instrument the agent layer so you can see what these systems do. Treat model provenance as a supply-chain problem, because it is one. Assume the text your systems read is hostile, because it demonstrably is. Keep a human in the loop on irreversible actions. Design for least privilege as if the model will be turned against you, because this year it sometimes was. Every one of those is worth doing if Coxon is completely wrong. Every one of those is worth doing if he is completely right. That is what a good control looks like — it pays off across the whole range of the disagreement.

Coxon’s real contribution, for my community, is not the timeline. It is the reminder that the curve has a top, and that the people closest to the summit are frightened enough to walk away from a great deal of money and status to say so. You can discount their forecast and still take their fear as data. Insiders defecting is itself a signal, the same way I treat any credible insider warning about any system: not proof, but a reason to look harder.

And fear, on its own, is not a security control. It never has been. The useful response to a frightening trajectory is not to panic and not to look away — it is to build the instrumentation, the provenance checks, and the least-privilege boundaries that hold up whether the scary version arrives in three years or never. That is unglamorous, it does not trend on X, and it is the only part of this whole debate I can actually hand you on a Monday morning.

And there is a version of this future worth being optimistic about, which I do not want to lose in the alarm. The “superhuman” in Coxon’s sentence is a system that outgrows us. The superhuman I want is a person — an analyst, a defender, a builder — amplified by tools they own and understand, which is the case I made in AI Must Make Superhumans, Not Unemployed. You can hold that optimism and still log your agents; done right, the two are the same project.

Take the warning seriously. Take the skeptics seriously. Then go log your agents.

Stay paranoid. Ground the fear in evidence. Build the controls that pay off either way.

Further Reading:

Questions or feedback? Reach out via:

Contact: info@vulnex.com

Posted in AI, Business, Economics, Privacy, Security, Technology, Threat Modeling | Tagged , , , , | Leave a comment